Best AI Tools for Debugging Code
I gave the free tiers of ChatGPT, Claude and Gemini seven deliberately nasty bugs, from an infinite loop to a JSON precision trap. All three found every one. The difference was what they warned me about.

Eddie Ochieng
July 6, 2026· Updated Oct 13, 2026
The real test of a coding assistant is not whether it can write new code. It is whether it can find the bug you have been staring at for an hour. Writing something fresh from a clean prompt is the easy half. Debugging is where a tool meets the mess of real work, a misleading error, a symptom three functions away from its cause, a thing that only breaks on a Tuesday. So I stopped asking these tools to build and started trying to break them. I wrote seven deliberately nasty bugs, each a different species, and handed them to the free tiers of ChatGPT, Claude and Gemini, with the symptom but never the cause. I expected at least one trap to beat at least one tool. I was wrong, and where I was wrong turned out to be the whole story.
How I tested
Seven bugs, each a different failure class, from an infinite loop to a floating-point trap to a shared-reference bug. Each tool got the exact same message, the code and a one-line symptom, never a hint about the bug itself. Same prompt every time. All three on their free tiers in October 2026, Claude on Sonnet 5.5, ChatGPT and Gemini on their default free models. Models move, so treat the specifics as a snapshot.
Finding the Bug Is No Longer the Hard Part
Here is the result that reorders everything else. All three tools found all seven root causes. Not just the gentle ones, all of them. The binary search that hung forever instead of crashing, so there was no stack trace to follow. The regex that ground to a halt only on a crafted string, the classic denial-of-service trap. The JSON number that silently dropped its last digit. The shared array hiding behind counts that looked perfectly correct. I built these to separate the tools on correctness, and on correctness they were inseparable. Every one diagnosed, every one fixed.
On the JSON bug, all three independently reached for context.source, a reviver argument added to JSON.parse only recently that most working developers have never touched. That is not pattern-matching the top Stack Overflow answer. That is current, specific knowledge, on the free tier, from all three at once. If your mental model of free AI is that it fumbles anything subtle, it is a year out of date.
The Bug That Looked Solved and Was Not
The one I would build the story around is the bug where everything appeared to work. A function groups words by their first letter, counting and collecting as it goes.
function groupByFirstLetter(words) {
  const base = { count: 0, items: [] };
  const groups = {};
  for (const w of words) {
    const key = w[0];
    if (!groups[key]) groups[key] = { ...base };
    groups[key].count++;
    groups[key].items.push(w);
  }
  return groups;
}
Feed it "apple", "avocado", "banana" and "banana" turns up inside group "a" as well as group "b". Every group’s list ends up holding all three words. The counts, though, are perfect. That is the trap. The counts being right is exactly what stops you suspecting the lists, and it is what would send a tired developer hunting in the wrong place for an hour.
All three tools spotted the shallow copy, that spreading base makes a new object but not a new array, so every group points at the same items. But the real tell was whether they explained why the counts stayed correct while the arrays merged, because that is the line between recognising a pattern and understanding a bug.
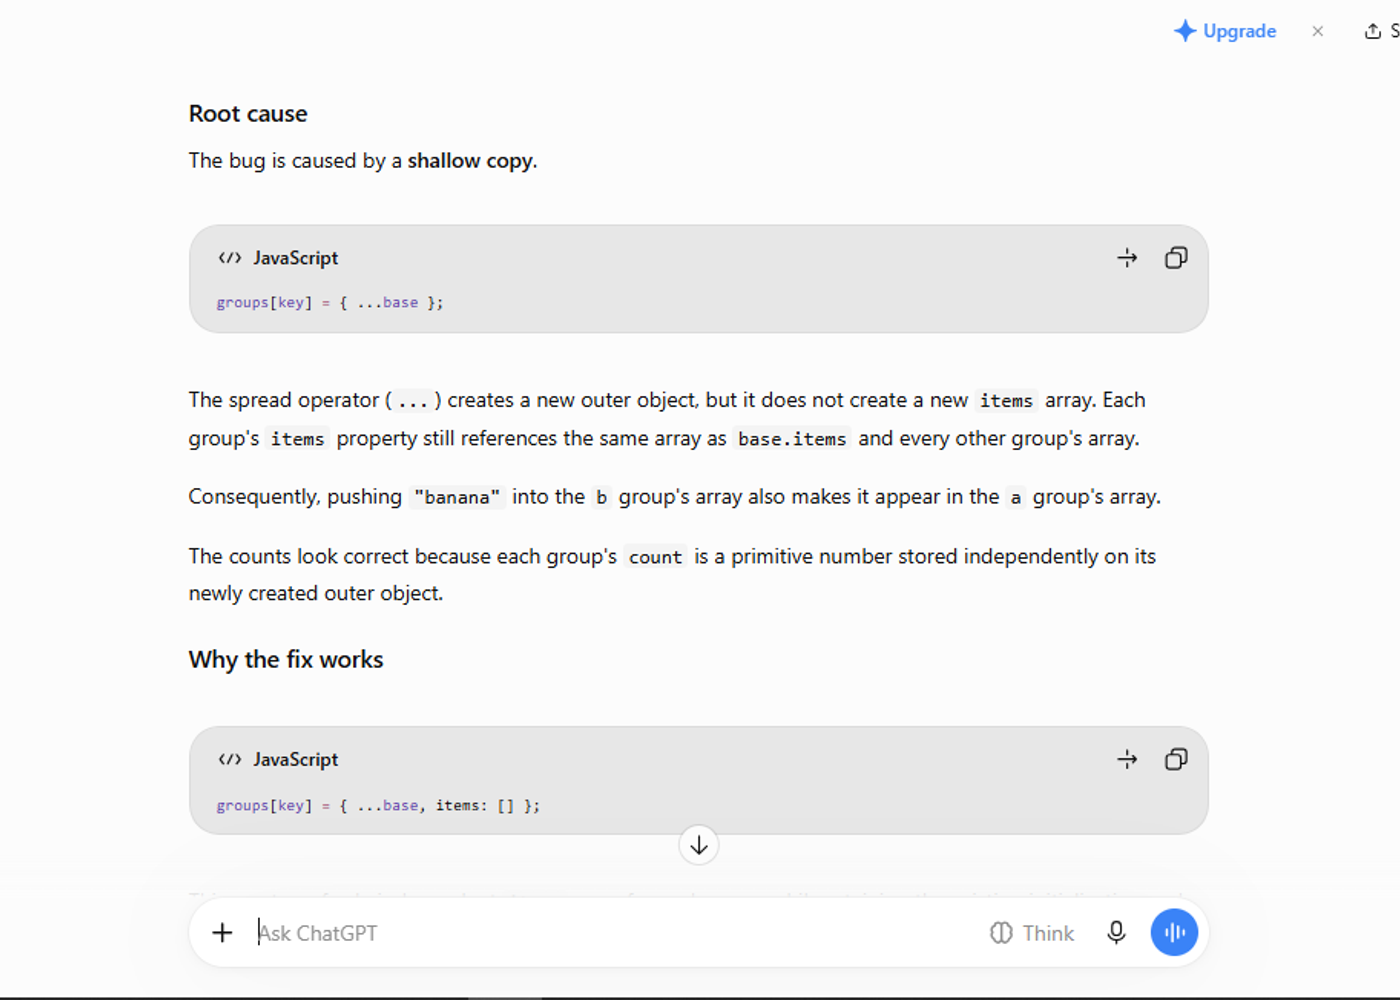
ChatGPT and Claude both nailed it: count is a primitive, copied by value onto each fresh object, so it reads fine, while items is a single shared array every group references. That one sentence is the entire bug. A tool that silences the symptom without explaining the count is a tool you cannot quite trust on the next one, because it may not have understood this one.
Where They Really Split, the Warnings
If the test had stopped at the fix, it would have been a three-way tie. It did not stop there. Take the nastiest of the seven, a JSON payload whose order id is a number just large enough to lose precision.
function parseOrderId(json) {
  const data = JSON.parse(json);
  return data.orderId;
}
// parseOrderId('{"orderId": 9007199254740993}') returns 9007199254740992
All three found it, correctly blamed JSON.parse itself rather than the function around it, and all three fixed it with the context.source reviver and BigInt. Then Claude did the thing that decided the whole test. It treated the fix as something going into a real system, not a puzzle to close.
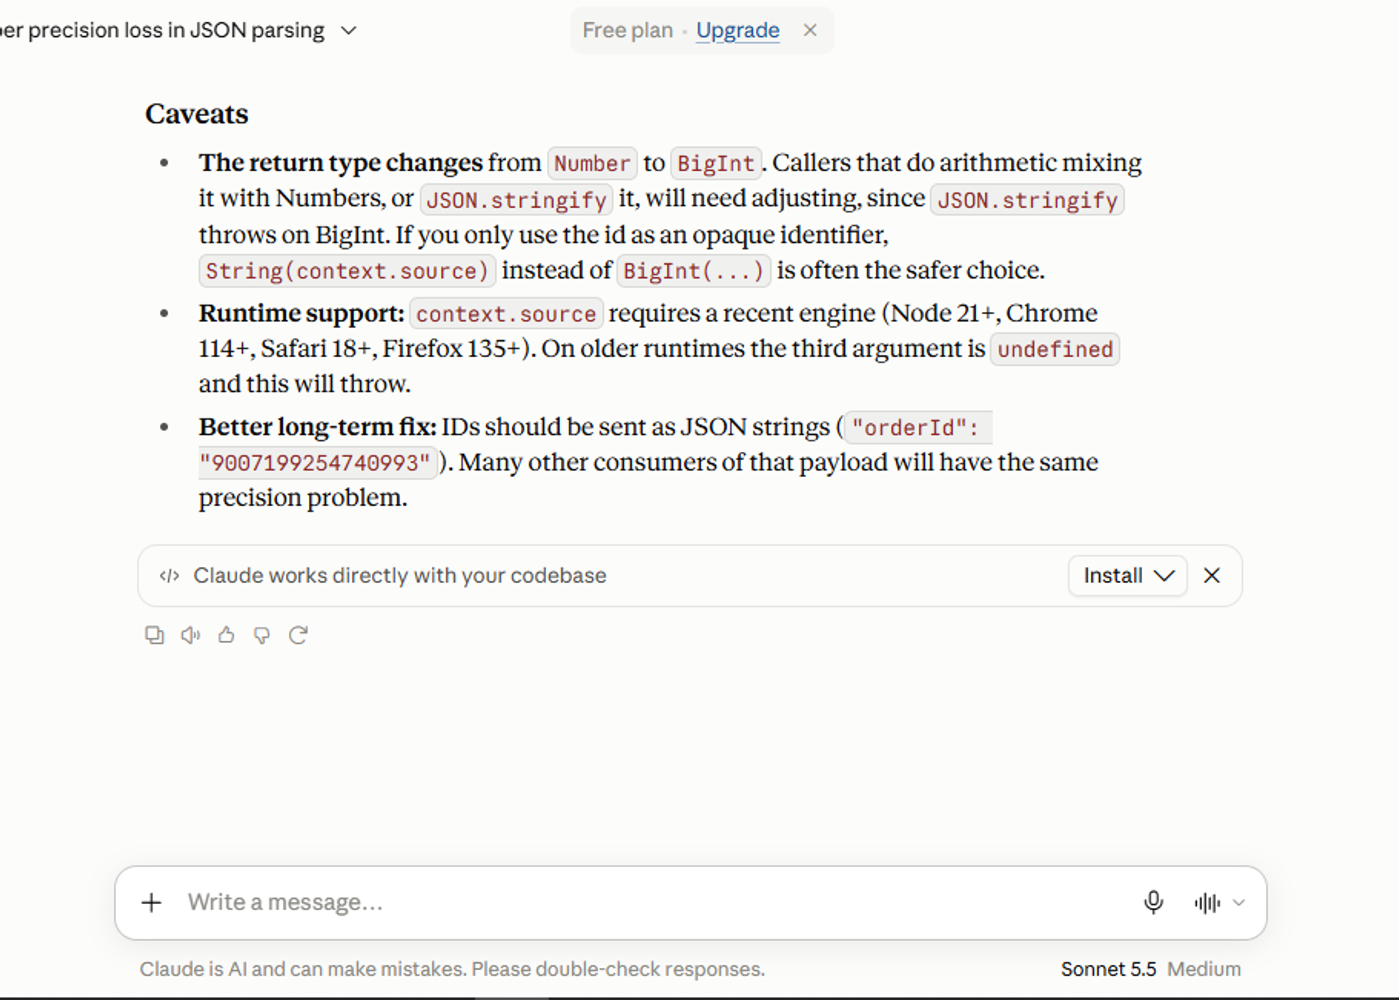
It warned that the return type now changes from a number to a BigInt, so any code that does arithmetic on the id or calls JSON.stringify will break, because stringify throws on BigInt. It warned that context.source needs a recent runtime, Node 21 or a current browser, and is undefined otherwise, which would make the fix itself throw. And it pointed at the real cure, that an id this size should be sent as a string in the first place. ChatGPT gave a clean, guarded fix and explained the precision limit well. Gemini fixed it too, then offered a regex shortcut that would shatter the moment the payload nested. But only one tool told me what its own fix would break.
Doing What You Asked, and Only That
There was one more split worth its own mention, because it is about judgement rather than knowledge. On an async caching bug, all three correctly saw that the code cached the resolved value instead of the in-flight promise, so five quick calls fired five requests. The fix is the same for everyone. What differed was the instruction. I had written, in the prompt, do not change anything else.
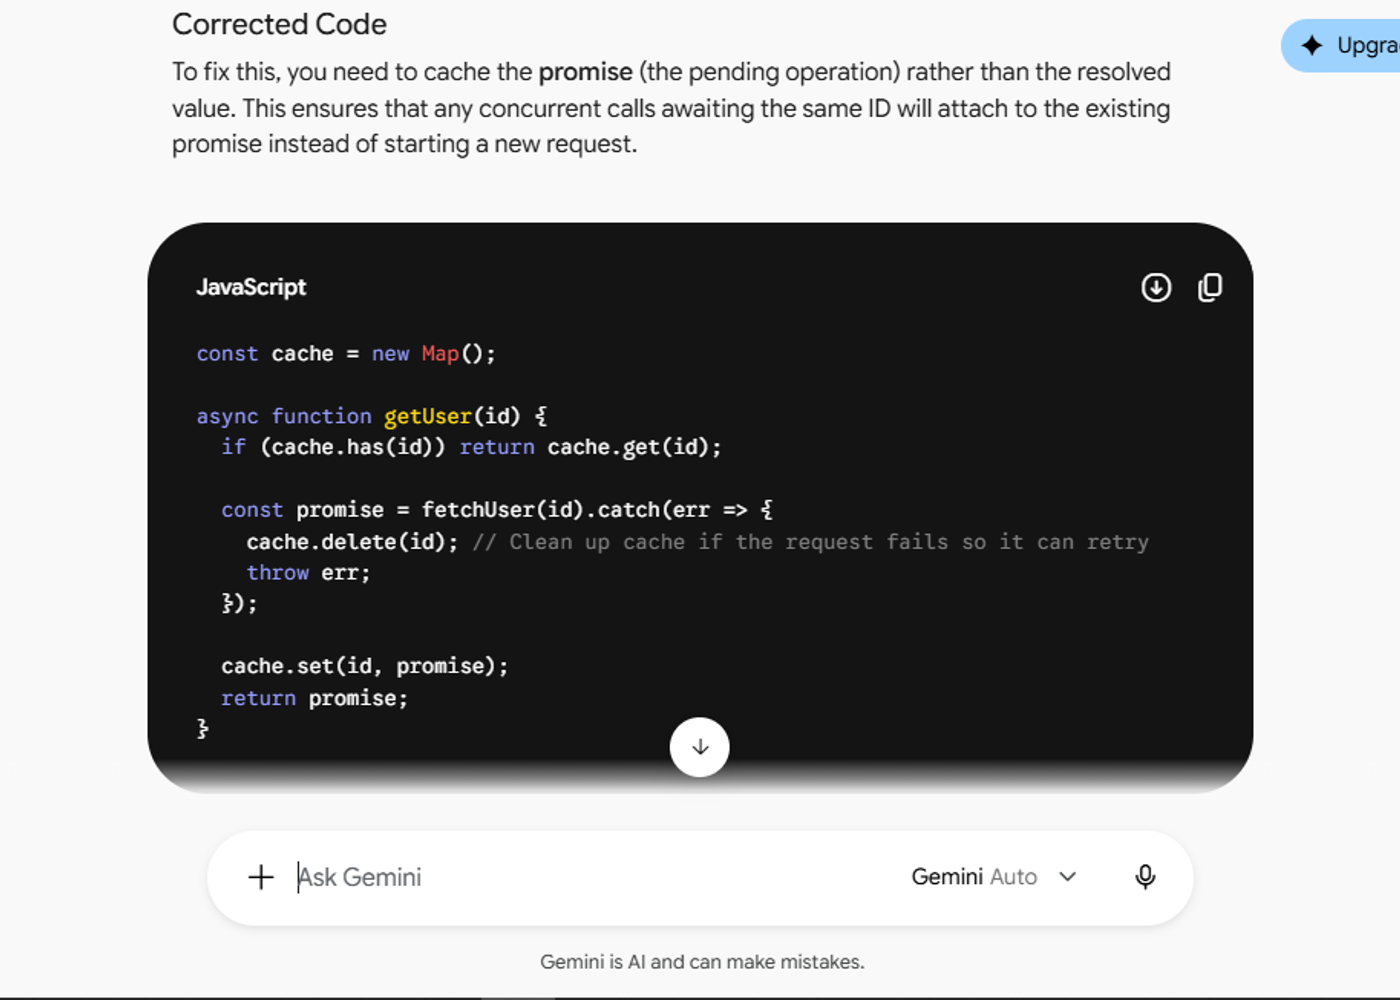
Claude and ChatGPT both noticed that a rejected promise would get stuck in the cache, and both left it as a note, honouring the brief and handing me the choice. Gemini went ahead and added the cleanup itself. Its version was arguably more robust. It was also not what I asked for. On someone else’s code, in a review where I am trying to understand a change before I trust it, the tool that flags the issue and waits is the one I want. Tell me, do not decide for me.
| Tool | Price | Best for |
|---|---|---|
| Claude | Free (Sonnet 5.5); Pro from ~$17/mo | Depth and judgement; it warns what a fix will break |
| ChatGPT | Free; Plus $20/mo | The clearest explanations and worked traces |
| Gemini | Free | Correct every time; the least cautious about side effects |
The catch
These tools are good enough to be dangerous. A confident fix that quietly changes behaviour is worse than no fix at all, because you will paste it and move on. The free tiers will debug almost anything you hand them now. The skill that still matters is reading the caveats, and never trusting a fix you do not understand.
How to Debug Well with Any of Them
- Give the symptom, not your theory. The moment you say "I think it is the loop", you have narrowed what it looks at. Describe what goes wrong and let it find why.
- Ask for the root cause, not a patch. "Fix this" gets the crash line silenced. "Find the real cause and explain it" gets the actual bug.
- Read what it says it changed. The dangerous fixes are the ones that quietly alter behaviour, so make the tool spell out what moved.
- Prefer the tool that warns you. A fix that comes with a caveat is worth more than a confident fix with none.
- Verify in your own codebase. Right on a snippet is not the same as right in your project. Run the test before you believe it.
This is one of a set. For the assistant you actually code inside day to day, see the best AI coding assistant. For the same free tools writing code rather than fixing it, seven of them wrote the same program and I judged whose I would trust. And to catch bugs before they ship, the best AI code review tools.
FAQ
What is the best AI tool for debugging code?+
In my test, all three free tiers (ChatGPT, Claude and Gemini) found and fixed seven hard bugs. Claude was the one I would trust most, because it consistently warned what its fix would break. For the clearest explanations and traces, ChatGPT.
Can free AI tools actually find real bugs?+
Yes, and better than most developers expect. On seven deliberately nasty bugs, including an infinite loop, a ReDoS and a JSON precision trap, all three free models found every root cause. Finding the bug is no longer the differentiator.
Is it safe to paste an AI’s bug fix straight into my code?+
Only if you understand it. The real risk now is a confident fix that quietly changes behaviour, like swapping a number for a BigInt. Read what the tool says it changed, and prefer one that flags the side effects.
Which is better for debugging, ChatGPT or Claude?+
Both found every bug in my test. Claude gave the deeper caveats about what each fix would break; ChatGPT gave the clearest traces and worked examples. For debugging specifically I leaned Claude.